
respan-gateway
Open-source LLM gateway in Rust. One endpoint for OpenAI, Anthropic, Gemini and every other vendor. Any SDK, any model, any tool.
Automatically checked · GitHub checked 2026-11-12
Overview

The universal adapter for AI.
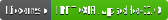


Respan Gateway is a single Rust binary that sits between your code and every AI API. Point the SDK you already use at it, and it connects you to everything: chat models, images, video and voice from every major provider; tools for any model, from web search and memory to code sandboxes and any MCP server; and traffic control (format translation, fallback, retries and hedged requests), with a live log of every call. ▶ Watch the demo
Key features
-
Any client, any model
OpenAI Chat Completions, OpenAI Responses, Anthropic Messages and Gemini API clients can all call any model, with streaming, tools, images and reasoning translated. -
Multimodal
Realtime voice across vendors (an OpenAI Realtime client talks to Gemini Live, and back), plus images, speech, transcription, embeddings and video through OpenAI's or Gemini's APIs, to any vendor that has them. -
MCP tools for every model
Put MCP servers or built-in tool vendors behind the gateway, from web search to code sandboxes. It runs their tools inside chat requests, so a plain chat call can use them, whatever the client or model. -
Traffic control
Named routes, globs andprovider/model; fallback, retries, cheapest or fastest; and hedged requests that race a slow call against a second provider. -
Observability
A live request log with cost, latency and tokens for every call, and traces in Respan, where span-02 analyzes how your agents behave. -
Best-in-class performance
0.07 ms of added latency, 56,000 requests per second and 31 MB of memory in our benchmarks: about 3× the throughput of the next fastest gateway we tested. -
Write your own plugin in minutes
Every feature above is a plugin, built on the same public Rust API you can use: one trait with four hooks. Start from the plugin guide or an example such as guardrails, PII masking or billing.
Quickstart
1. Install
pip install respan-gateway
Or cargo install respan-gateway, or a
GitHub release.
2. Run it with your keys
export OPENAI_API_KEY=sk-...
respan-gateway
No config file needed: every vendor whose key is set becomes a provider.
3. Call any model from any SDK
from anthropic import Anthropic

client = Anthropic(base_url="http://localhost:8080", api_key="unused")
reply = client.messages.create(
    model="gpt-6-luna", max_tokens=256,
    messages=[{"role": "user", "content": "Hello from the Anthropic SDK"}])
print(reply.content[0].text)
The web UI is at localhost:8080/ui/. Next: configuration and MCP tools.
Other ways to run it
- Python, in-process — Run the gateway inside your Python app, with no server.
- Embed in Rust — Mount the gateway in your own Rust service.
- Docker —
docker run -p 8080:8080 -e OPENAI_API_KEY -e RESPAN_CLIENT_KEYS=<a key of yours> ghcr.io/respanai/respan-gatewayon any container host; listening beyond localhost, it needs a client key.
Performance
| Respan Gateway | Bifrost | Portkey | LiteLLM (1 worker) | |
|---|---|---|---|---|
| Added latency (p50) | 0.07 ms | 0.16 ms | 0.17 ms | 4.34 ms |
| Throughput | 56,734/s | 18,182/s | 4,187/s | 268/s |
| Memory | 31 MB | 488 MB | 350 MB | 418 MB |
| 1k streams, success | 100% | 92–100% | — | 79% |
| 1k streams, memory | 128 MB | 688 MB | — | 493 MB |
| p99, 5% slow calls | 105 ms | 2,002 ms | 2,003 ms | 2,024 ms |
Configuration
You don't need a config file to start. When you want more, run
respan-gateway init for a commented gateway.toml. One file sets up keys,
providers, traffic control, tools and tracing:
client_keys = [{ name = "app", key = "env:APP_KEY" }]   # who may call the gateway

[providers.openai]                      # a built-in vendor: just add a key
vendor = "openai"
key = "env:OPENAI_API_KEY"

[providers.anthropic]
vendor = "anthropic"
key = "env:ANTHROPIC_API_KEY"

[providers.local]                       # any OpenAI-compatible endpoint
formats = ["openai-chat"]
base_url = "http://localhost:8000/v1"

[routes.smart]                          # clients ask for "model": "smart"
to = ["anthropic/claude-haiku-5-5", "openai/gpt-6-luna"]
hedge = "800ms"                         # race the second if the first is slow

[tools.search]                          # web search as MCP tools
vendor = "linkup"
key = "env:LINKUP_API_KEY"

[plugins.tool_loop]                     # every model can use them
servers = ["search"]

[plugins.respan]                        # trace every call in Respan
key = "env:RESPAN_API_KEY"
respan-gateway check validates it, and --watch or SIGHUP reloads it
without a restart. Without client keys, the gateway answers only on loopback
and refuses to start on a public address.
Reference: configuration ·
vendors · tool vendors ·
MCP and tools · gateway.example.toml
Reading: From the GPU to your bill: a deep dive into prompt caching
Supported API formats
Call the gateway in any format on the left, and it reaches every provider on the right, translating between them.
| Your code calls | It can reach | |
|---|---|---|
| Chat | OpenAI Chat Completions OpenAI Responses Anthropic Messages Gemini API |             any chat model, whichever of the four formats it speaks |
| Realtime voice | OpenAI Realtime Gemini Live | OpenAI ⇄ Gemini voice; Mistral for transcription |
| Images | OpenAI Images Gemini Images | Amazon Bedrock's Stability AI models |
| Speech, transcription | OpenAI Speech OpenAI Transcriptions | |
| Embeddings | OpenAI Embeddings |   |
| Video | OpenAI Videos Gemini Veo |  Google Veo |
| Decisions | Respan Decisions TypeSafe System One Gemini Decisions |   |
| Tools | MCP |  |
| Anything else | A vendor's own API | Relayed to that vendor untouched |
Each vendor's formats are in vendors, and the translation details in each format's README: chat, media, realtime and decisions.
Plugins
Everything the gateway does is a plugin on one public Rust API.
Models · 16 providers and any compatible endpoint, each reachable from any client format. All vendors →


Tools · any MCP server, plus built-in tools for search, browsing, code, documents and memory, usable from any model. All tool vendors →






Traffic control · named routes, fallback, retries, hedged requests, and the cheapest or fastest provider.
Observability · a live request log, the cost of every call, and traces in Respan.
Your framework · anything with a base URL. Guides for the OpenAI SDK, Anthropic SDK, Google GenAI, Vercel AI SDK, LangChain, Pydantic AI, Pi, OpenCode and more.
Your own plugin · start from the plugin guide or an example: guardrails, PII masking, billing, an LLM judge.
Built in: routing · tool-loop · mcp-router · pricing · respan · responses · credentials
Community
Contributions are welcome. CONTRIBUTING.md covers the architecture, building and tests, and a new vendor is usually one file. Start with a good first issue, ask in Discussions or Discord, and report security issues as SECURITY.md describes.
Roadmap: what we're building next is in issues. Missing a vendor, format or feature? Ask for it.
Want it managed? Respan runs the gateway for you, with dashboards, evals and span-02.
License
Dual-licensed under MIT or Apache-2.0, at your option.