
open-jet
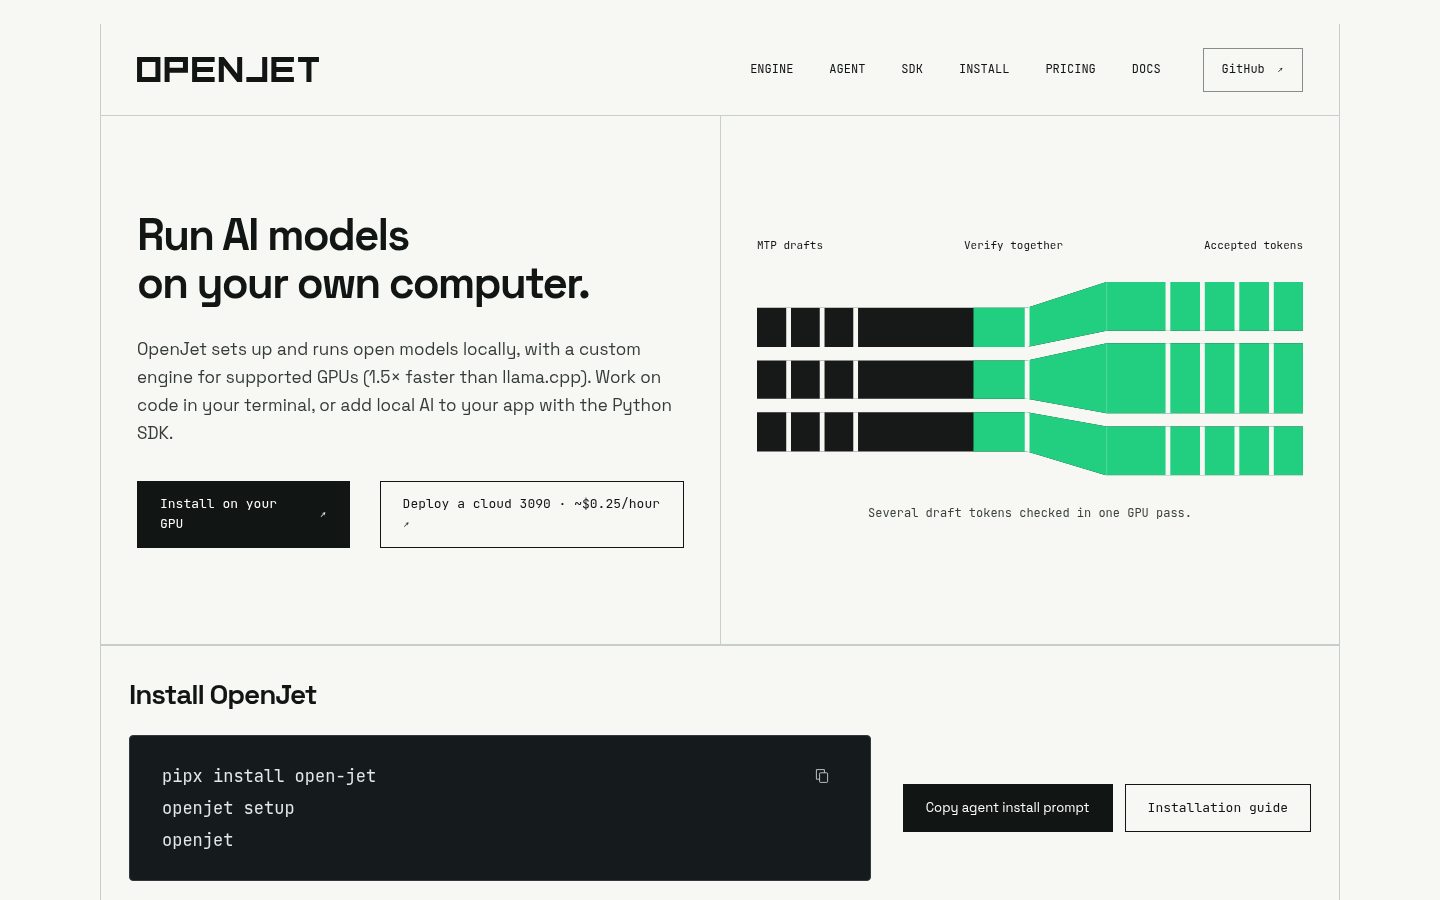
An offline coding agent for local models. One command sets up the best model your GPU can run, and on 24 GB+ RTX 30/40/50-series cards Qwen3.8-27B runs up to 2.6x faster than llama.cpp.
Automatically checked · GitHub checked 2026-11-17
Overview
Run Qwen3.8-27B on your own GPU, 2x faster than llama.cpp.
For NVIDIA RTX 30, 40 and 50-series cards with 24 GB. Use it with Claude Code, Codex, OpenCode, OpenClaw or OpenJet's own agent. Runs offline.
No 24 GB card? Deploy a cloud RTX 3090 with OpenJet and Qwen3.8-27B ready to use, about $0.25/hour on Vast.ai.
Speed · Install · Hardware · Coding tools · 4 agents · Docs


English · 简体中文
Speed
| RTX 3090, Qwen3.8-27B Q4_K_M | llama.cpp | OpenJet |
|---|---|---|
| Thinking on, short prompts | 61 tok/s | 121 tok/s (2.0x) |
| Thinking on, 98K tokens in context | 37 tok/s | 96 tok/s (2.6x) |
| Reading a 98K-token prompt | 112 s | 76 s (1.5x) |
- One conversation on one RTX 3090, not a batch. 106K-token context, q8_0 KV cache, thinking on, temperature 1.0,
top_p 0.95, top_k 20, 1,024 tokens per reply; 5 prompts and one 98K-token prompt
(
engine_compare.py). - llama.cpp b11982 with MTP speculative decoding (2 drafts) and flash attention, measured 2026-10-29; OpenJet's engine at 7 drafts, measured 2026-11-17. Same harness and settings; one of the 5 short prompts and the text of the 98K prompt differ between the two runs.
- Same output as llama.cpp on the same weights: top-token agreement 98.74%, KL divergence 0.0016, against 98.25% and 0.0023 for llama.cpp's own batched mode (results).
Context on a 24 GB card: about 120K tokens, or about 234K with openjet setup --long-context
(KV cache presets).
Install
pip install open-jet
openjet setup      # finds your GPU, downloads the model and OpenJet's prebuilt engine for it
openjet            # OpenJet's own coding agent
openjet serve      # or serve the model to Claude Code, Codex, OpenCode or OpenClaw
More: docs/installation.md
What you need
Linux and an NVIDIA RTX 30, 40 or 50-series GPU with 24 GB (sm_86, sm_89, sm_120), driver 580 or newer.
openjet setup downloads OpenJet's engine prebuilt for your GPU (which one).
No 24 GB card? Deploy a cloud RTX 3090 with OpenJet and Qwen3.8-27B ready to use, about $0.25/hour on Vast.ai.
More: docs/installation.md
4 coding agents on one GPU
Up to 4 agents decode in the same pass over the weights: about 420 tok/s in total on an RTX 3090 on short prompts, 360 tok/s with about 23K tokens of context each.
More: docs/features.md
Results on your GPU
openjet bench --github <your-handle> measures your card with a fixed workload. Send the file in a
pull request to benchmarks/community/ (what a run measures).
No results yet. Run openjet bench and send yours; the first row could be your card.
More: benchmarks/community/README.md
Use it with your coding tools
openjet serve speaks Anthropic Messages, OpenAI Responses and OpenAI Chat Completions;
openjet connect claude-code (or codex, opencode, openclaw) prints the settings.
More: docs/features.md
OpenJet's terminal agent
A coding agent built for a model that fits on your GPU: bounded context, automatic condensing, approved shell commands, resumable sessions, skills and MCP.
More: docs/features.md
Python SDK
Embed a local model in your application.
More: docs/features.md
Also: tuned to the hardware · Ollama, LM Studio or llama-server · FAQ
Built on OpenJet
- geezuz-qwen3.8-27b-dual-gpu: OpenJet's engine split across 2 GPUs (tensor-parallel, 2x RTX 3090 over P2P)
- qwen38-megakernel: OpenJet's engine developed further as a standalone server, with a CPU vision encoder; OpenJet's engine now comes from it
Built something on OpenJet? Open a pull request to add it here.
Docs
- Start: Getting started · Quickstart · Installation · Configuration · Choosing a model · Overview
- Coding tools: Claude Code, Codex, OpenCode and OpenClaw
- Runtime: OpenJet's engine · llama.cpp · Benchmarking
- Agent: CLI · Slash commands · Slipstream · Skills · MCP · Device sources · Workflow harness · Session state and logging
- SDK: Quickstart · Python SDK
- For AI tools and writers: AGENTS.md · Install with an agent · AI reference · Media kit
- Deployment: Jetson · Linux x86 + NVIDIA · CPU-only
Community and license
Discord · X / Twitter · AGPL-3.0-only (licensing, CONTRIBUTING.md, CLA.md)