
freelingo
Open-source, self-hosted AI language learning platform with local or cloud LLMs, CEFR study plans, an AI tutor, voice conversations, flashcards, and spaced repetition.
Automatically checked · GitHub checked 2026-11-12
Before you switch
Evaluate hosting, migration and feature requirements before switching.
Overview
FreeLingo



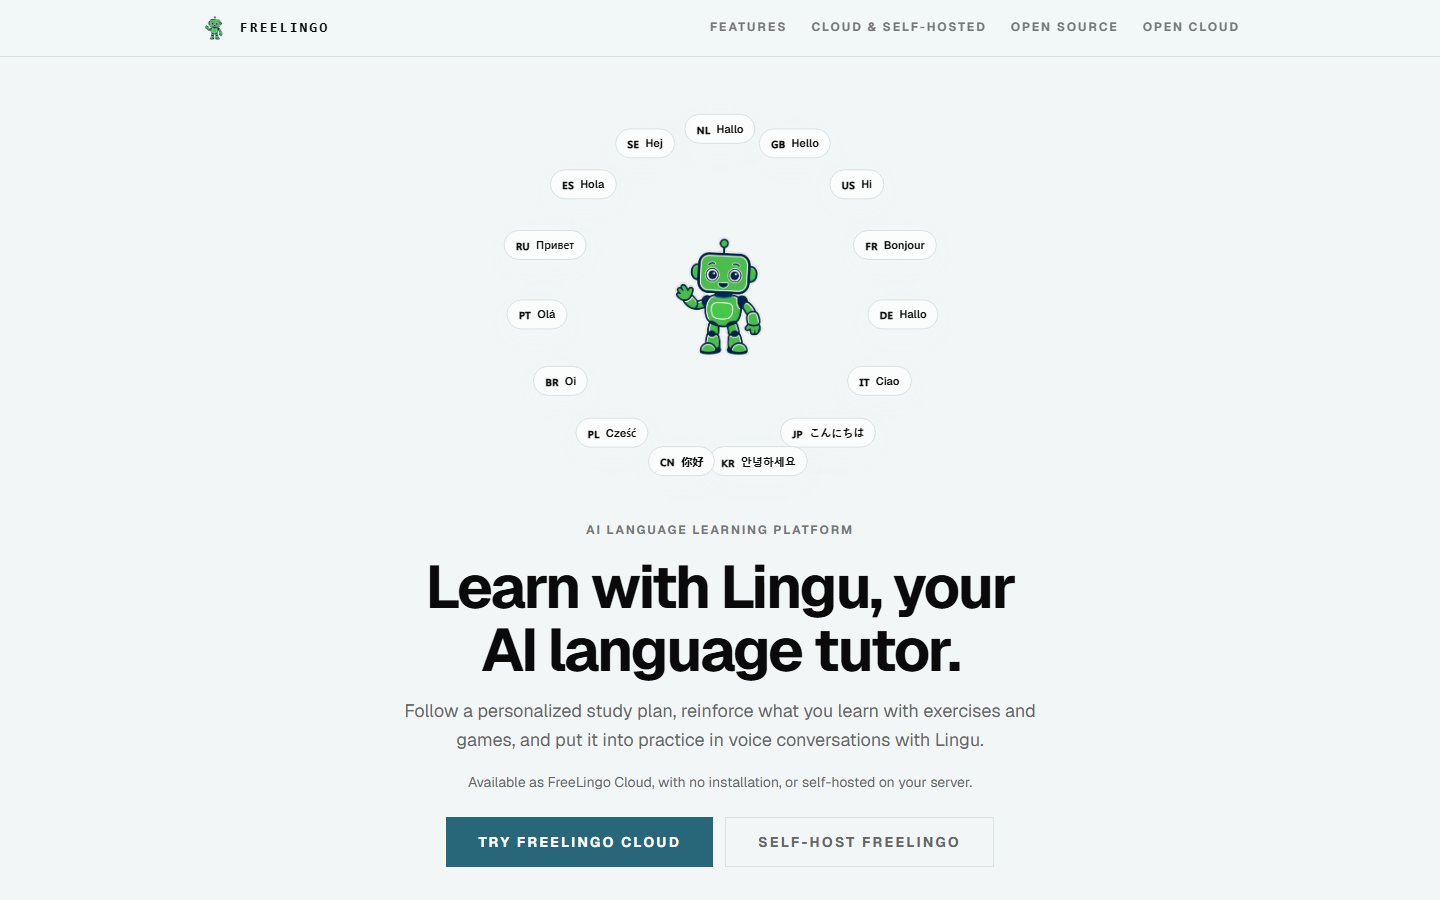
Structured learning. Everyday practice. Conversations with Lingu.
Overview
FreeLingo is an open-source language learning platform with a structured A1–C2 curriculum and an AI tutor, Lingu. Use the managed service or run the application on your own infrastructure.
- Find your starting point. Take the adaptive placement quiz or start at A1 as a beginner. Quiz scoring and study-plan scheduling are deterministic; the plan follows the selected language's curriculum, level, and duration of 4, 8, 12, or 16 weeks.
- Follow your plan. Work through curriculum units with clear competencies and prerequisites. Lesson content is AI-generated within those boundaries, with native-language explanations and practice across grammar, vocabulary, comprehension, and writing.
- Practise with Lingu. Use text and voice tutoring with user-controlled memories. Completed lessons also offer voice practice: confirm a topic preview, then discuss the lesson with help informed by your exercise answers. These conversations retain the existing voice limits and appear in chat history under the lesson topic.
Alongside the plan:
- Review and explore: SM-2 flashcards, grammar and vocabulary resources, a phrasebook, generated Listening and Reading exercises, and pronunciation practice.
- Practise grammar topics: add references to a personal grammar library, complete saved five-question practices, and track results across plans in the same language. Completed practices can continue in voice with Lingu, informed by the topic and your answers.
- Learn through games: Error Detective, Sentence Order, and Vocabulary Pairs. Review completed lessons, prepare familiar foundations for the next lesson, or practise at your plan's level. Sessions are saved for later, with language-specific history and plan-owned XP; freemium access uses a shared daily game quota.
- See your progress: XP, streaks, skill scores, unit competencies, and end-of-level tests. The dashboard highlights today's XP, seven days of activity, and plan progress. Rewards recognise lessons, reviews, meaningful tutor participation, and unit/level completion; activity uses UTC dates.
- Learn multiple languages: keep separate plans, progress, flashcards, and learning attempts for each study language. Account settings, subscription, quotas, and tutor memories remain global.
Architecture · Quick start · Configuration · Speech setup
Hosted service
FreeLingo Cloud — start learning without managing a server.
Visit freelingo.app for the managed service, with a free plan and paid subscriptions. No Docker, GPU, or server maintenance required from the learner.
The hosted instance is operated by the FreeLingo team. Self-hosting remains free and open source under AGPL-3.0; you manage your deployment and its infrastructure/provider costs. Accounts and progress belong to each installation.
For businesses
Need FreeLingo for your team or organisation?
- Private / on-premise deployment: run FreeLingo on your infrastructure and control configuration, storage, and provider selection.
- Dedicated managed instance: setup, hosting, maintenance, and updates for your organisation in a dedicated environment.
- Commercial licence: deploy a customised or white-labelled version under separately agreed terms. See COMMERCIAL_LICENSE.md.
Get in touch via the contact form to discuss your requirements.
Support continued development through GitHub Sponsors.
Architecture
The monorepo combines a Next.js frontend and a FastAPI backend, deployed with Docker Compose.
- Frontend: presentation, navigation, and browser audio capture/playback.
- Backend: business logic, authentication, persistence, and all LLM, TTS, and STT integrations.
- Storage: PostgreSQL 16 for durable application data; Redis 7 for sessions and operational state.
The frontend never calls AI or speech providers directly.
See the architecture specification for system structure and the Docker specification for runtime and image details.
Repository
Browse the project structure
freelingo/
├── assets/                          # Logos and static assets
├── backend/                         # FastAPI (Python)
├── blender/                         # Lingu source model and animations
├── data/                            # Shared data files
├── docs/                            # GitHub Pages landing site
├── frontend/                        # Next.js (React)
├── messages/                        # Interface translation catalogs
├── scripts/                         # Local toolchain, formatting, and validation
├── specs/                           # Specification files
├── AGENTS.md                        # AI assistant instructions
├── CHANGELOG.md                     # Version history
├── CODE_OF_CONDUCT.md               # Community guidelines
├── COMMERCIAL_LICENSE.md            # Commercial licence terms
├── CONTRIBUTING.md                  # Contribution guidelines
├── CONTRIBUTOR_LICENSE_AGREEMENT.md # CLA for contributors
├── DEVELOPMENT.md                   # Local development setup
├── docker-compose.yml               # Production deployment
├── docker-compose.dev.yml           # Development deployment
├── LICENSE                          # AGPL-3.0 licence
├── README.md                        # This file
└── run-dev.sh                       # Development helper script
Stack
- Frontend: Next.js 16, shadcn/ui, Tailwind CSS, Zustand, next-intl
- Backend: FastAPI, SQLAlchemy async, Alembic, Pydantic v2
- Data: PostgreSQL 16 and Redis 7
- LLM: Ollama, OpenAI, Anthropic, or DeepSeek
- Speech: Kokoro-FastAPI, OpenAI, or Gemini TTS; faster-whisper or OpenAI Whisper
- Auth: JWT access and refresh tokens with admin/user roles
- Deployment: Docker Compose
Quick start
Choose Docker Compose for a command-line deployment or Portainer for stack management.
Server prerequisites
- Docker and Docker Compose; Git for the clone-based setup.
- A supported cloud LLM API or Ollama.
- An NVIDIA GPU for the default local speech containers, or cloud speech credentials (OpenAI for STT; OpenAI or Gemini for TTS).
- For production voice: HTTPS and reverse-proxy routing for
/ws/*, as explained below.
Choose your speech providers before starting the stack. The default Compose
file includes GPU containers for both local speech services; selecting a cloud provider in .env does not
disable those containers automatically.
Option A — Git clone + Docker Compose
1. Clone and configure
git clone https://github.com/artcc/freelingo.git
cd freelingo
cp .env.example .env
Edit .env: configure DATA_PATH, database and Redis credentials, SECRET_KEY, and your LLM and
speech providers. Review the remaining settings in .env.example.
2. Prepare the model — only when using Ollama
Run on the Ollama host:
ollama pull gemma4:e4b
3. Start the stack
docker compose up -d
Pending database migrations run automatically each time the backend starts.
Open http://localhost:3000 (or http://<server-ip>:3000 for HTTP access from another machine).
Production microphone access requires the HTTPS setup described below.
By default, the first registered user becomes an administrator; set FIRST_USER_IS_ADMIN=false to
disable this behavior.
Option B — Portainer (Stack)
- Open Portainer → Stacks → Add stack.
- Choose Repository and enter the repo URL, or paste the contents of
docker-compose.ymldirectly into the Web editor. - Add the variables from
.env.example. At minimum, configureDATA_PATH, thePOSTGRES_*values,REDIS_PASSWORD,SECRET_KEY, and the selected LLM and speech providers and credentials. - Click Deploy the stack.
- Access the app at
http://<server-ip>:3000. Database migrations run automatically when the backend starts.
Ollama on the same host: use
OLLAMA_BASE_URL=http://host.docker.internal:11434. On Linux, if that hostname does not already resolve, addhost.docker.internal:host-gatewayunder the backend'sextra_hosts. Production Compose does not include this mapping.
Operational notes
AI providers
- Language model:
LLM_PROVIDERselectsollama,openai,anthropic, ordeepseek. The recommended Ollama model isgemma4:e4b; configure another through.env. - Speech:
TTS_PROVIDERselectslocal(Kokoro),openai, orgemini;STT_PROVIDERindependently selectslocal(faster-whisper) oropenai. See speech setup.
OpenAI and Anthropic model settings
- OpenAI LLM requests use the Responses API, with
OPENAI_MODEL=gpt-6-lunain.env.example. The selected model and endpoint must support Responses; a Chat Completions-only gateway is insufficient. FreeLingo manages conversation context and sendsstore=false. - Optional
OPENAI_REASONING_EFFORTapplies to OpenAI chat, memory-tool turns, and content generation. Leave it empty for the model default. Values arenone,minimal,low,medium,high,xhigh, andmax, subject to model support; there are no model-specific overrides. - Ollama and DeepSeek use Chat Completions; Anthropic uses its native API.
ANTHROPIC_MAX_TOKENSdefaults to8192and must fit the selected model's output limit.
See the service contracts for provider behavior.
Limits and access
Conversation, token, freemium, and trial limits are configurable in .env.example.
For session-count, minute, and token quotas, 0 means unlimited; for freemium feature quotas,
0 blocks the feature. Conversation duration and inactivity settings have their own bounds.
See subscriptions and quotas.
FREEMIUM_GRAMMAR_PRACTICE_DAILY defaults to three new practices per account/UTC day, shared across
study languages and independent of Games. Saved sessions remain available after exhaustion;
Premium, active trials, and Stripe-disabled deployments bypass this free generation allowance.
Web subscriptions use Stripe Checkout. Optional REVENUECAT_ENABLED=true synchronizes a shared
Premium entitlement through RevenueCat while retaining Stripe payments and the existing web interface.
It requires STRIPE_ENABLED=true, provider credentials, webhook configuration, and importing existing
subscriptions before activation. See the RevenueCat setup and operating contract
and .env.example.
Study languages
Choose from 20 study languages, counting each regional variant separately, and learn one or several side by side. Each has its own A1–C2 curriculum, placement test, grammar reference, vocabulary and phrasebook.
- Chinese: Mainland Mandarin, in simplified characters (
zh-CN). - Croatian: Croatia (
hr-HR). - Czech: Czechia (
cs-CZ). - Danish: Denmark (
da-DK). - Dutch: Netherlands (
nl-NL). - English: British (
en-GB) and American (en-US). - Finnish: Finland (
fi-FI). - French (
fr-FR). - German (
de-DE). - Italian (
it-IT). - Japanese (
ja-JP). - Korean: South Korea (
ko-KR). - Polish (
pl-PL). - Portuguese: Brazilian (
pt-BR) and European (pt-PT). - Romanian: Romania (
ro-RO). - Russian (
ru-RU). - Spanish: Spain (
es-ES). - Swedish: Sweden (
sv-SE).
Choose your first language during onboarding, then add more from Settings → My Languages.
Your plans, progress and flashcards stay separate for each language, including regional variants.
On self-hosted installations, AVAILABLE_TARGET_LANGUAGES controls which options are available.
Your native language is a separate choice made during registration. It is used for translations, explanations and tutor feedback to support you while you learn.
The interface language is another independent choice in Settings. It controls menus and interface text without changing your native language or the languages you study. Maintainer implementation guides: adding a study language and adding an interface or native language.
Linux host: Redis memory overcommit
Redis requires vm.overcommit_memory=1 on the host for reliable background saves (RDB snapshots).
Without it, a fork() under low memory can fail and unsaved data may be lost on restart.
Run once on the server:
sudo sysctl vm.overcommit_memory=1
echo "vm.overcommit_memory = 1" | sudo tee -a /etc/sysctl.conf
The first command applies the setting immediately; the second persists it across reboots. This is a host-level setting and cannot be applied from within the container without elevated privileges.
Reverse proxy requirement (real-time conversation)
[!IMPORTANT] Production voice conversation needs HTTPS for microphone access and WebSocket routing to the backend. Next.js HTTP rewrites do not forward WebSocket upgrades.
Route /ws/* to backend:8000, including the /ws/conversation connection. The production frontend
derives its WebSocket URL from window.location.
Browser microphone access requires a secure context such as HTTPS or localhost; ordinary HTTP access through a server IP does not provide it.
Configuring TTS & STT
TTS and STT are required services, selected independently via .env. Both default to local providers.
TTS_PROVIDER=localuses Kokoro-FastAPI;openaiuses OpenAI TTS;geminiuses Gemini TTS.STT_PROVIDER=localuses faster-whisper;STT_PROVIDER=openaiuses OpenAI Whisper.OPENAI_API_KEYis required when either service uses OpenAI.GEMINI_API_KEYis required only whenTTS_PROVIDER=gemini.
Local speech
The default local services in docker-compose.yml are configured for NVIDIA GPUs:
TTS_PROVIDER=local
STT_PROVIDER=local
The default Kokoro voice is af_heart. FreeLingo does not automatically select a Kokoro voice from
the study language. OpenAI TTS supports the language-aware pronunciation guidance described in the
speech specification.
For CPU-only local deployment, select CPU images, remove GPU reservations, and use a smaller Whisper model as documented in the Docker specification.
Cloud speech
OpenAI providers require no local GPU or speech containers:
TTS_PROVIDER=openai
STT_PROVIDER=openai
OPENAI_API_KEY=sk-...
Remove the corresponding kokoro and/or whisper service blocks from your deployment Compose file
when using cloud providers for those services; changing the provider variables alone does not remove their
GPU reservations.
For Gemini TTS, select TTS_PROVIDER=gemini and set GEMINI_API_KEY on the backend. The default model
is gemini-3.8-flash-tts; configurable female/male voices produce native WAV audio. STT remains an
independent local or OpenAI choice. Settings stores the Gemini voice preference separately from OpenAI.
OpenAI speech services reuse OPENAI_API_KEY when OpenAI is also the LLM provider. See .env.example for
available settings and the speech-services specification for
provider contracts.
Development
See DEVELOPMENT.md for the repository-local toolchain and validation workflow on macOS and glibc-based Linux. It covers setup, focused tests, static checks, and environment recreation.
Contributing
Bug reports, feature suggestions, documentation improvements, and code contributions are welcome.
- Contribution guide — read before opening an issue or pull request.
- Code of conduct — community expectations.
By opening a pull request you accept the Contributor License Agreement.
License
Distributed under the GNU Affero General Public License v3.
Organisations that need to deploy FreeLingo without the AGPL's copyleft obligations can obtain a commercial licence. See COMMERCIAL_LICENSE.md or get in touch via the contact form.
Author
Arturo Carretero Calvo — @artcc